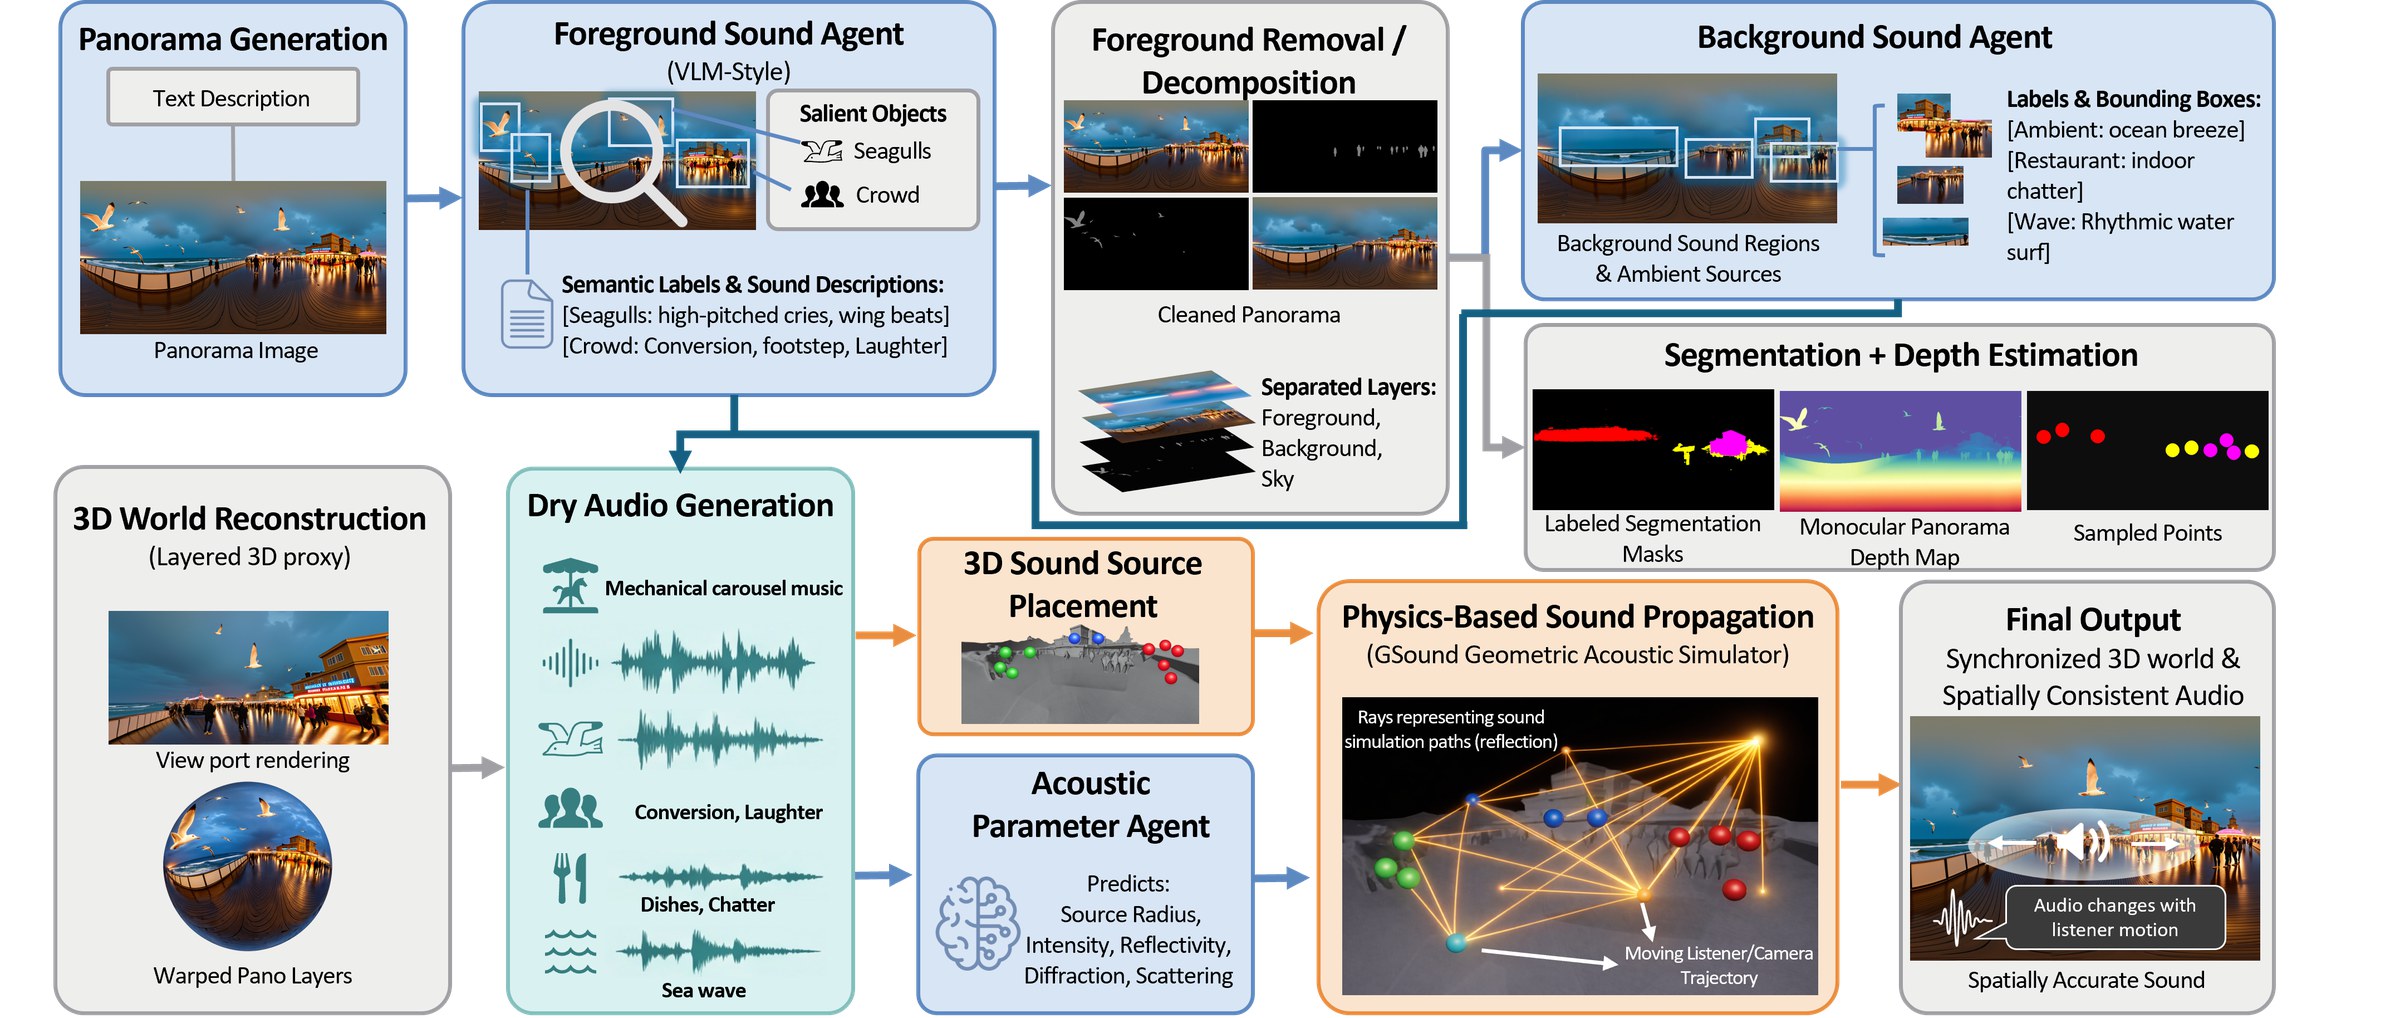
A training-free framework that turns generated visual worlds into explicit audible world states with semantic sound sources, geometric grounding, and listener-dependent acoustic propagation.
Text- and image-conditioned world generators can create visually rich 3D environments, yet these worlds often remain silent or rely on soundtracks synthesized solely from text or rendered video. Although such audio can convey what should be heard, it lacks an explicit representation of where sound sources are located and how their perceived sound should vary with listener movement.
We introduce Audible World Models, a training-free framework that incorporates sound into the generated world state. Starting from a text prompt, our system constructs a panoramic 3D proxy, separates it into semantic layers, identifies sound-producing foreground objects and ambient background regions, and synthesizes dry audio for each sound label. It then anchors these sources to reconstructed geometry and renders listener-dependent spatial audio using geometric acoustic propagation. By explicitly linking semantics, geometry, and sound propagation, the framework maintains persistent source locations while adapting the rendered audio to changes in listener viewpoint and motion.
Experiments across 80 generated scenes demonstrate substantial gains in spatial consistency over text-, video-, and panorama-conditioned baselines, while preserving competitive semantic alignment. VLM-based assessments and human evaluations further indicate that our soundtracks are preferred for their audio–visual consistency, spatial plausibility, and motion-dependent behavior.
A text prompt is converted into a global panorama and layered 3D proxy, giving the system access to audible sources that may sit outside the current rendered view.
VLM agents parse foreground objects and broader background regions, assign concise sound descriptions, and mark each source as localized or diffuse for later spatialization.
Text-to-audio synthesis produces dry clips for each label. Localized sounds are placed on object meshes or world sheets, and diffuse sounds are distributed over semantic background regions.
An acoustic parameter agent selects stable scene and source settings, then GSound renders binaural, listener-dependent audio through geometry-aware propagation along the trajectory.
Each scene compares three soundtracks for the same camera trajectory: Stable Audio Generation (text-conditioned), MMAudio (video-conditioned), and Ours.
Headphones recommended to hear the spatial (binaural) effects. Videos and audio are compressed for the web.
A watercolor panorama of a windy beach concert, distant stage lights and crowd shapes, foreground as broad wet sand wash, no text.
A metal foundry with a glowing ladle edge and heat shimmer in the foreground, workers midground in protective gear, and towering furnaces with overhead cranes in the background, photoreal, no text.
A distant panorama of a crowded beach boardwalk, dense movement and kiosks in the distance, foreground kept as open sand strip, photoreal, no text.
A Monet-inspired impressionist scene of a wide meadow with distant poplars and a pale sky, foreground kept as soft color fields, no text.
A distant view of a large outdoor concert in a park, stage lights and crowd concentrated midground, foreground kept as empty grass and sky, photoreal, no text.
A wide view of a riverfront festival at night, a dense band of lights and crowds across the midground, foreground kept as dark open water, photoreal, no text.
A wide desert highway at night, a long line of distant headlights and taillights, foreground kept as empty sand and scrub, cinematic realism, no text.
A broad view of a factory yard, forklifts and loading docks active in the distance with flashing lights, foreground kept as an empty paved apron, photoreal, no text.
A temple courtyard in rain: a close stone lantern and wet tiles in the foreground, visitors midground under umbrellas, and a gate with hanging bells in the background with mist, photoreal, no text.
A school hallway between classes: a close row of lockers and posters in the foreground, students midground, and a bright stairwell and doors in the background, photoreal, no text.
A rural grain elevator site: a close gravel shoulder and road sign in the foreground, trucks midground, and tall silos with conveyor structures in the background under a wide sky, photoreal, no text.
A Monet-inspired impressionist view of a crowded riverside fair, colorful dots of people and lanterns across the midground, foreground as soft open water and reflections, no text.
A large rail yard panorama, multiple freight trains and signal lights in the distance, foreground mostly empty ballast and track edges, photoreal, no text.
A wide panorama of a container port at dawn, cranes and forklifts active in the distance with flashing beacons, foreground mostly open water and empty pier edge, photoreal, no text.
A busy commercial kitchen: a stainless prep counter with utensils in the foreground, cooks moving midground, and stoves with vents and shelves in the background under harsh task lighting, photoreal, no text.
A train station platform at dusk: a luggage suitcase and yellow safety line in the foreground, commuters waiting midground, and an arriving train with signal lights in the background beneath a long canopy, photoreal, no text.
A low-poly stylized scene of an open prairie with a distant wind farm, simple shapes, big sky, minimal foreground objects, no text.
A watercolor illustration of a wide coastal horizon with soft waves and distant sailboats, lots of negative space, gentle washes, no text.
A high mountain plateau with distant snow peaks, broad open rock and sparse grass, foreground kept empty, wide-angle realism, no text.
A downtown street parade at noon, with marching performers, confetti in the air, storefront reflections, crowd barriers, and a cross street filled with sunlight, realistic wide-angle.
A small village square, with a fountain in the center, people chatting near the shops, and a bicycle passing along the edge of the square.
A subway tunnel platform, with a train approaching in the distance, footsteps along the platform, and scattered voices under the station lights.
A beach at golden hour, with waves breaking on the left, children playing near the water, and seagulls circling above.
A working orchard during harvest, with long rows of trees, crates and ladders, a small tractor on a dirt lane, and a gravel road leading to a shed, photoreal natural light.
A windswept coastal village quay with boats and fluttering flags, post-impressionist painting inspired by Vincent van Gogh, bold swirling strokes, dramatic sky, vivid color, no text.
A riverside summer festival at sunset, with a small live band on an open-air stage, food trucks and string lights along the path, crowds moving between stalls, and water reflecting the last light, cinematic wide shot.
@inproceedings{chen2026audible,
  title     = {Audible World Models: Spatially Aware Sound Generation for 3D Worlds},
  author    = {Chen, Duowen and He, Jinjin and KV, Gouthaman and Bangalore Venkatesh, Sandeep and Zhu, Bo},
  booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
  year      = {2026}
}